Data Lake with AWS: Governance, Scalability and Insights in the Cloud
CloudDog offers a highly efficient Data Lake solution that leverages the powerful AWS Cloud services to streamline data organization and analysis. Our architecture includes AWS Lake Formation for centralized and secure data catalog management, ensuring robust governance and simplified discovery. We use S3 for storage, Glue for ETL, Athena for queries, and Step Functions with EventBridge for automation.
Features
- AWS Lake Formation for Centralized Governance: Enables efficient and secure Data Lake management, with granular access control, activity monitoring, and regulatory compliance, ensuring a trustworthy environment for data storage and analysis.
- Amazon S3 with Layered Structure: The scalable and secure storage of Amazon S3 is organized into Bronze, Silver, and Gold layers, allowing ingestion of raw data, intermediate transformations, and optimizations for strategic analyses. This structure promotes operational efficiency and accessibility for various teams.
- AWS Glue for ETL Pipelines: Provides advanced transformations and automation of ETL processes, ensuring that data is prepared for real-time analysis and strategic reporting. The solution includes partitioning and compression to maximize performance.
- Amazon Athena for Scalable Queries: Offers fast and reliable queries directly in the Data Lake, enabling ad hoc analyses and critical decision support, all without needing to provision additional infrastructure.
- AWS Step Functions and Amazon EventBridge for Automated Orchestration: Automates data processing workflows, ensuring that the different stages of the pipeline are executed reliably, scalably, and monitored.
- AWS DMS for Data Migration: Ensures secure and efficient data transfer from on-premises or other cloud databases to the AWS Data Lake, using a VPN Site-to-Site for enhanced security and reliability.
- Glue Data Catalog for Data Discovery: Centralizes and organizes the Data Lake metadata, facilitating the discovery, classification, and usage of data by different tools and teams, promoting reuse and efficient management.
- AWS Secrets Manager for Secure Credential Management: Simplifies the management and protection of credentials and secrets required for integration with external systems and data sources, ensuring compliance and connection security.
- Amazon EMR for Advanced Data Processing: Amazon EMR enables you to run big data frameworks such as Apache Spark, Hadoop, and Presto directly on data stored in the Data Lake. It is ideal for complex analytics, machine learning, and distributed workloads, and automatically scales to efficiently manage large clusters.
- Machine Learning and Amazon SageMaker Integration: The Data Lake, organized into tiers (Bronze, Silver, and Gold), provides a robust foundation for training machine learning models on Amazon SageMaker. Native integration with services such as AWS Glue DataBrew makes it easy to prepare data for predictive and prescriptive analytics, while Amazon Forecast and Amazon Comprehend can be used to create predictive insights and advanced text analytics.
Architecture
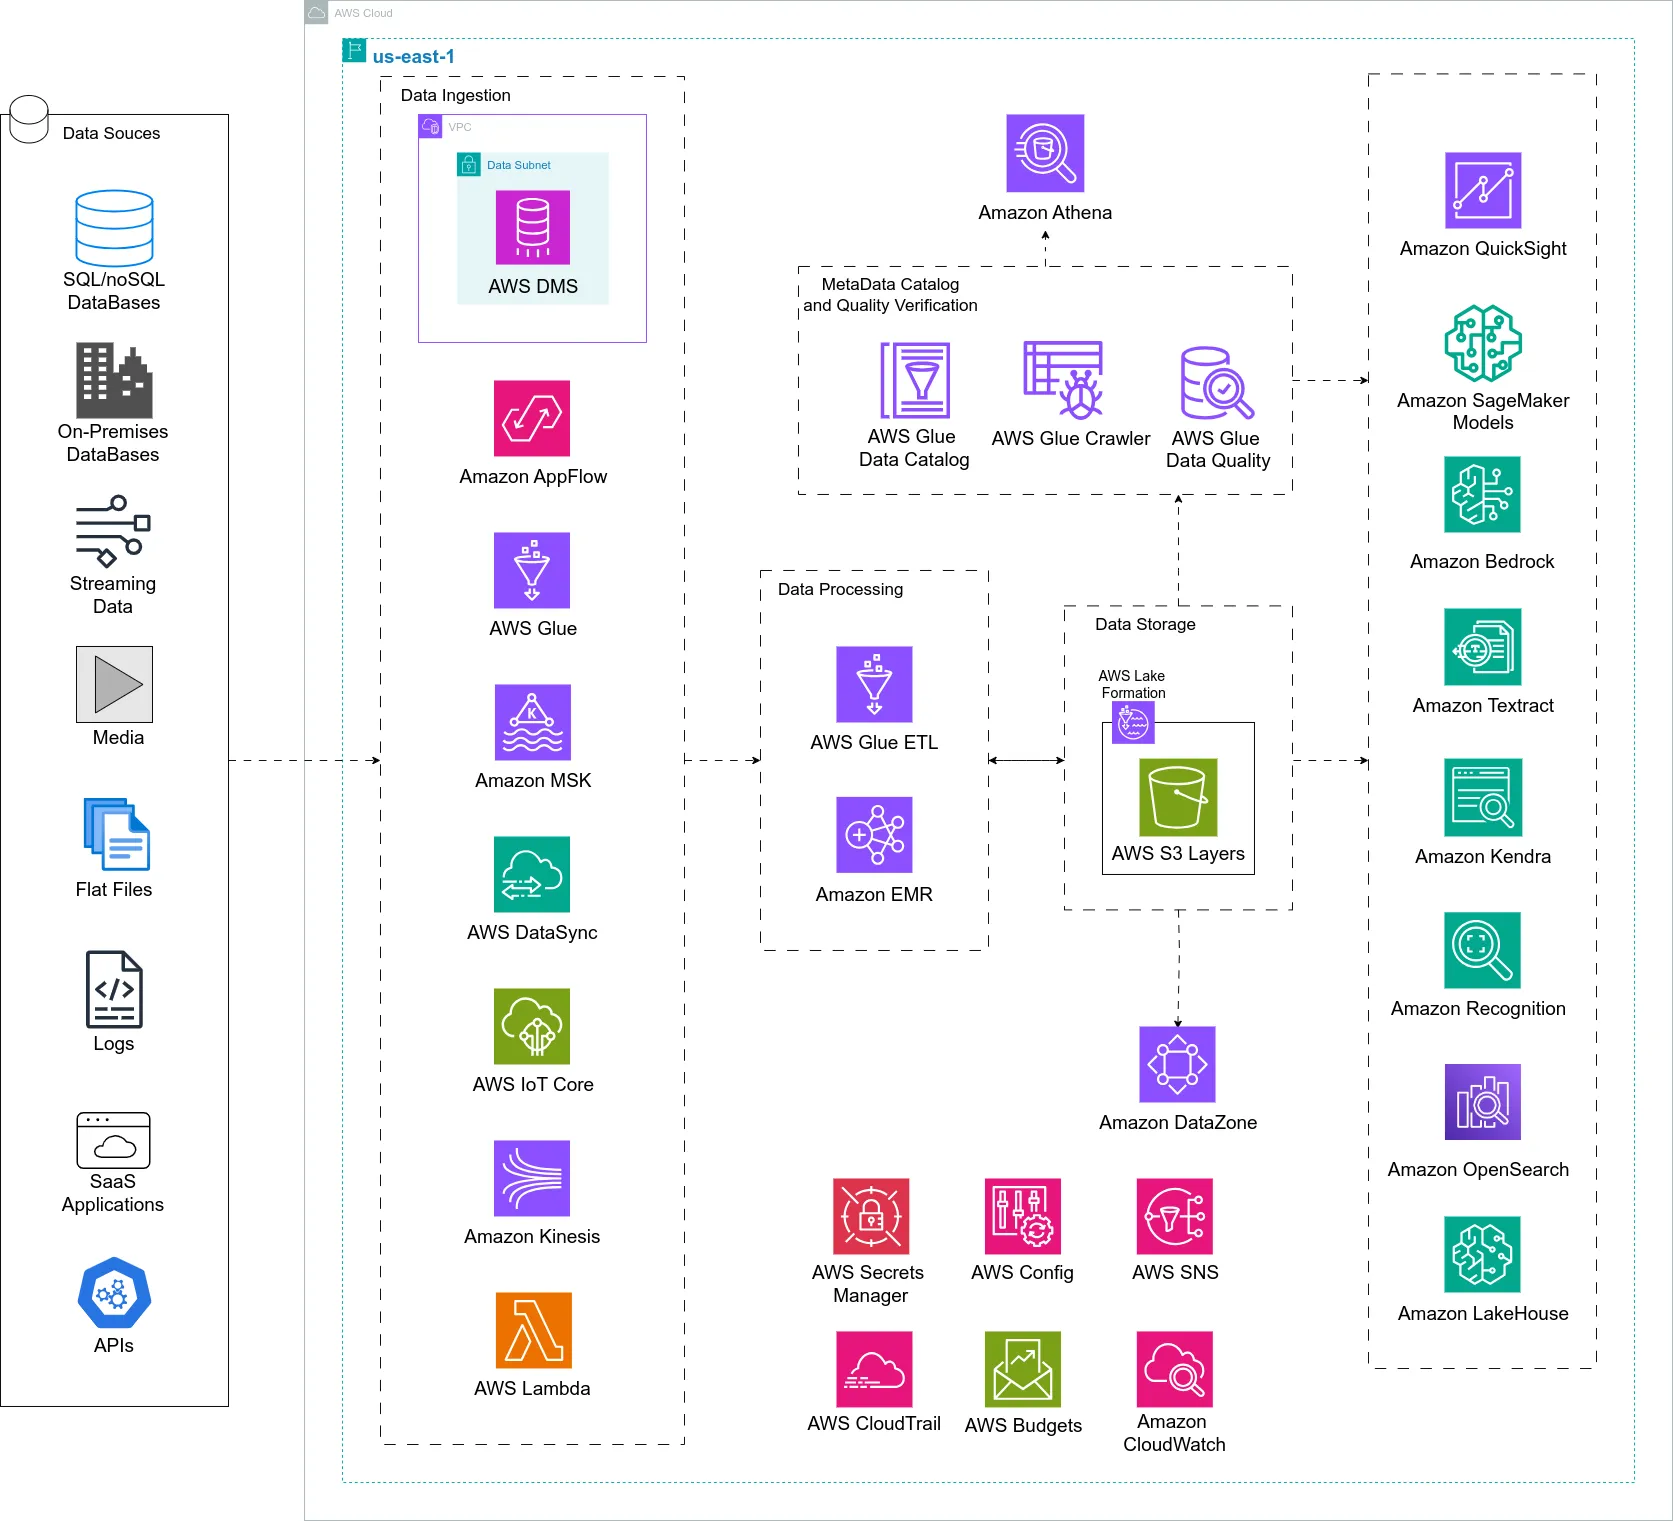
For this solution, we provide case-specific architectures, offering alternatives to typical Data Lake implementations with varying levels of scalability, cost efficiency, and process automation. Each architecture is designed to address specific use cases, including data ingestion via APIs, integration with external databases, highly complex scenarios with advanced governance, and real-time data streaming.
Use Case
- Data Lakes for High-Volume Processing: Perfect for companies managing large data volumes, such as banks, insurers, or industries with multiple data sources.
- Analytics for Strategic Decision-Making: Ideal for organizations that need optimized and ready-to-use data for fast analysis, such as BI companies or marketing departments using machine learning to predict trends.
- Storage and Processing of Complex Data: Great for scenarios requiring the processing of heterogeneous and unstructured data, such as system logs, media files, or large datasets used in scientific research.
- Storage and Processing of Real-Time Data: Excellent for scenarios that require real-time data capture, processing, and storage, such as clickstream, video stream, log stream, and others.
- Data Compliance and Security: Essential for organizations that must comply with strict regulations like GDPR, LGPD, or HIPAA, ensuring the protection of sensitive data and the implementation of robust access controls. Ideal for sectors like healthcare, finance, and government, where data governance and auditing are crucial.
- Machine Learning and Artificial Intelligence: Essential for companies that want to explore predictive and prescriptive analytics, using data organized in the Data Lake to train machine learning models. The Data Lake serves as the basis for AI solutions in areas such as content personalization, demand forecasting, and sentiment analysis. With integration with services such as Amazon SageMaker, it is possible to develop and deploy models directly on the stored data.